Showing posts with label Hadoop Contents. Show all posts

Wednesday, 24 June 2015

Spark-Part2

What is Apache Spark?
Why it is a hot topic in Big Data forums?
Is Apache Spark going to replace hadoop?
If you are into BigData analytics business then, should you really care about Spark?
I hope this blog post will help to answer some of your questions which might have coming to your mind these days.

Introduction to Apache Spark

It is a framework for performing general data analytics on distributed computing cluster like Hadoop.It provides in memory computations for increase speed and data process over mapreduce.It runs on top of existing hadoop cluster and access hadoop data store (HDFS), can also process structured data in Hive and Streaming data from HDFS,Flume,Kafka,Twitter
Spark Architecture

Is Apache Spark going to replace Hadoop?

Hadoop is parallel data processing framework that has traditionally been used to run map/reduce jobs. These are long running jobs that take minutes or hours to complete. Spark has designed to run on top of Hadoop and it is an alternative to the traditional batch map/reduce model that can be used for real-time stream data processing and fast interactive queries that finish within seconds. So, Hadoop supports both traditional map/reduce and Spark.
We should look at Hadoop as a general purpose Framework that supports multiple models and We should look at Spark as an alternative to Hadoop MapReduce rather than a replacement to Hadoop.
Hadoop Echo System

Hadoop MapReduce vs. Spark –Which One to Choose?

Spark uses more RAM instead of network and disk I/O its relatively fast as compared to hadoop. But as it uses large RAM it needs a dedicated high end physical machine for producing effective results
It all depends and the variables on which this decision depends keep on changing dynamically with time.


Difference between Hadoop Mapreduce and Apache Spark

Spark stores data in-memory whereas Hadoop stores data on disk. Hadoop uses replication to achieve fault tolerance whereas Spark uses different data storage model, resilient distributed datasets (RDD), uses a clever way of guaranteeing fault tolerance that minimizes network I/O.For details see the UC Berkeley's link Resilient Distributed Datasets: A Fault-Tolerant Abstraction for In-Memory Cluster Computing.
From the Spark academic paper: "RDDs achieve fault tolerance through a notion of lineage: if a partition of an RDD is lost, the RDD has enough information to rebuild just that partition." This removes the need for replication to achieve fault tolerance.

Do I need to learn Hadoop first to learn Apache Spark?

No, you don't need to learn Hadoop to learn Spark. Spark was an independent project . But after YARN and Hadoop 2.0, Spark became popular because Spark can run on top of HDFS along with other Hadoop components. Spark has become another data processing engine in Hadoop ecosystem and which is good for all businesses and community as it provides more capability to Hadoop stack.
For developers, there is almost no overlap between the two. Hadoop is a framework in which you write MapReduce job by inheriting Java classes. Spark is a library that enables parallel computation via function calls.
For operators to running a cluster, there is an overlap in general skills, such as monitoring configuration, and code deployment.

Apache Spark's features

Lets go through some of Spark's features which are really highlighting it in the Big Data world!
From http://spark.apache.org/:


i) Speed:

Spark enables applications in Hadoop clusters to run up to 100x faster in memory, and 10x faster even when running on disk. Spark makes it possible by reducing number of read/write to disc. It stores this intermediate processing data in-memory. It uses the concept of an Resilient Distributed Dataset (RDD), which allows it to transparently store data on memory and persist it to disc only it’s needed. This helps to reduce most of the disc read and write – the main time consuming factors – of data processing.
Logistic regression in Hadoop and Spark

ii) Ease of Use:

Spark lets you quickly write applications in Java, Scala, or Python. This helps developers to create and run their applications on their familiar programming languages and easy to build parallel apps. It comes with a built-in set of over 80 high-level operators.We can use it interactively to query data within the shell too.
Word count in Spark's Python API
datafile = spark.textFile("hdfs://...")
datafile.flatMap(lambda line: line.split())
        .map(lambda word: (word, 1))
        .reduceByKey(lambda x, y: x+y)

iii) Combines SQL, streaming, and complex analytics.

In addition to simple “map” and “reduce” operations, Spark supports SQL queries, streaming data, and complex analytics such as machine learning and graph algorithms out-of-the-box. Not only that, users can combine all these capabilities seamlessly in a single workflow.

iv) Runs Everywhere

Spark runs on Hadoop, Mesos, standalone, or in the cloud. It can access diverse data sources including HDFS, Cassandra, HBase, S3.

Spark’s major use cases over Hadoop

  • Iterative Algorithms in Machine Learning
  • Interactive Data Mining and Data Processing
  • Spark is a fully Apache Hive-compatible data warehousing system that can run 100x faster than Hive.
  • Stream processing: Log processing and Fraud detection in live streams for alerts, aggregates and analysis
  • Sensor data processing: Where data is fetched and joined from multiple sources, in-memory dataset really helpful as they are easy and fast to process.
Note : Spark is still working out bugs as it matures.

Your Turn: Go Get Started

Spark is very easy to get started writing powerful Big Data applications. Your existing Hadoop and/or programming skills will have you productively interacting with your data in minutes. Go get started today:

Wednesday, 17 June 2015

Hadoop Basic Terms

Before knowing about Hadoop, we need to be aware about some basic terminologies: -

1) Node: - A computational resource which participates in a computational job by performing some
    computational tasks within a network is called node.

2) Cluster: - A group of nodes connected to each other through a common and dedicated network to form a distributed system is called cluster.

3) Hadoop node: - Any computational node which has both hadoop distributed file system (HDFS) and Map Reduce (MR) components in it is called as hadoop node.

4) Hadoop cluster: - A group of hadoop nodes connected to each other through a common and dedicated network is called as Hadoop Cluster. 

5) File System: - A file system is the underlying structure a computer uses to organize data on a hard disk.

Hadoop has two major components: -

1) HDFS

2) MAPREDUCE


                                                                     1) HDFS

HDFS stands for Hadoop Distributed file system, it is a shared file system used by by all the slave nodes of Hadoop distributed system. It is meant for Storage.

                                                                     2) MAPREDUCE

This component is used for data analysis. This component is implemented in Java programming language.

                                                                3) HADOOP CLUSTER


As seen in the cluster above, every computational node including the master node has two components: -
1) HDFS
2) MAPREDUCE

The main computational job is divided into a no of computational tasks and each task is handled by a slave node. In a hadoop cluster, the master node is called name node and all the slave nodes are called as data nodes. The name node is connected to all its data nodes through a common and dedicated network like VPN.

Saturday, 23 May 2015

What is Bigdata (Hadoop ) and Why ?

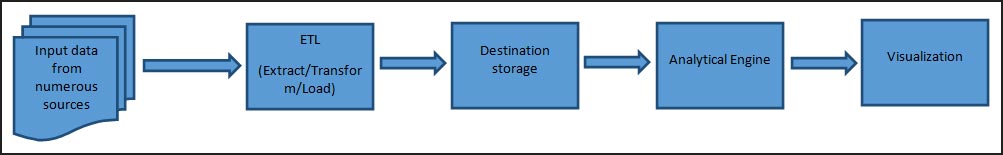
Bigdata  is buzzword these days and every industry ranging from small scale to enterprise level is looking at it and trying to solve their problems and derive hidden insights from the data. More sophisticated algorithms, platforms, advanced tools from numerous vendors are getting released into the market and everyone is trying to solve problems in different way. Complete picture of Bigdata problem solving will go through the below mentioned phases.
big data
Input Sources: Logs data, Streaming real time data, Sensor data, existing databases (MySql, Oracle etc.)
ETL Tools: Oracle BI Tools, Talend, Pentaho, Clover etc.
Destination Storage: HDFS, HBase, Cassandra, DynamoDB, AWS S3, GreenPlum, MongoDB etc.
Analytical Engine: R engine, Machine Learning engine etc.
Visualization: Tableau, Google charts, Leaflet, Highcharts etc.
In the above picture, it says that the data has to get moved from source to destination, destination to analytical engines, engines to visualization tools.
If all the above steps are performed using a single platform so that data will not get moved into different location is the desired platform in this current world. This saves valuable resources like network, bandwidth, time and latencies. Databricks is the product that is getting emerged these days to solve this issue.
Features of Databricks product:
  • Interactively analyze, visualize, and curate your data – big or small. Leverage Python, SQL, or Scala and seamlessly weave together advanced analytics, streaming data and interactive queries. Collaborate with colleagues in real-time to discover insights.
  • Build live dashboards that capture insights from your data exploration. Allow colleagues to interact with and customize visualizations. Automatically update dashboards and underlying queries in response to changing data.
  • Scale the insights you’ve discovered by building data products that deliver value to your business and customers. Schedule execution of notebooks you’ve built or standard Spark jobs – either periodically or based on changes in the underlying data.
  • Dynamically provision and scale managed clusters. Seamlessly import data – from S3, local uploads, and a variety of other sources. Fault tolerance, security, and resource isolation provided out of the box. Advanced management and monitoring tools to understand usage.
Databricks is powered by the 100% open source Apache Spark – the most active project in the Big Data ecosystem. Spark lets you explore your data in SQL, Python, Java, or Scala, and integrates machine learning, graph computation, streaming analytics, and interactive queries. The Databricks platform is the best place to develop and deploy Spark applications. Databricks is 100% compatible with the Apache Spark API. This allows users to leverage applications from the rapidly growing Spark ecosystem, and developers to easily develop Spark applications and deploy them on any Certified Spark distribution – in the cloud or on-premise.
The survey results indicate that 13% are already using Spark in production environments with 20% of the respondents with plans to deploy Spark in production environments in 2015, and 31% are currently in the process of evaluating it. In total, the survey covers over 500 enterprises that are using or planning to use Spark in production environments ranging from on-premise Hadoop clusters to public clouds, with data sources including key-value stores, relational databases, streaming data and file systems. Applications range from batch workloads to SQL queries, stream processing and machine learning, highlighting Spark’s unique capability as a simple, unified platform for data processing.
So there is lot of scope for spark with scala combo and its necessary to make everyone hands dirty in spark environment for a better future.

Wednesday, 13 May 2015

Hadoop Daemons Generated Logs

Apache Hadoop’s jobtracker, namenode, secondary namenode, datanode, and tasktracker all generate logs. That includes logs from each of the daemons under normal operation, as well as configuration logs, statistics, standard error, standard out, and internal diagnostic information. Many  users aren’t entirely sure what the differences are among these logs, how to analyze them, or even how to handle simple administrative tasks like log rotation.  This blog post describes each category of log, and then details where they can be found for each Hadoop component.
The log categories are:
·         Hadoop Daemon Logs
These logs are created by the Hadoop daemons, and exist on all machines running at least one Hadoop daemon. Some of the files end with .log, and others end with .out. The .out files are only written to when daemons are starting. After daemons have started successfully, the .out files are truncated. By contrasts, all log messages can be found in the .log files, including the daemon start-up messages that are sent to the .out files. There is a .log and .out file for each daemon running on a machine. When the namenode, jobtracker, and secondary namenode are running on the same machine, then there are six daemon log files: a .log and .out for the each of the three daemons.
The .log and .out file names are constructed as follows:
hadoop-<user-running-hadoop>-<daemon>-<hostname>.log
where <user-running-hadoop> is the user running the Hadoop daemons (this is always ‘hadoop’ with Cloudera’s distribution), <daemon> is the daemon these logs are associated (for example, namenode or jobtracker), and <hostname> is the hostname of the machine on which the daemons are running.
For example:
hadoop-hadoop-datanode-ip-10-251-30-53.log
By default, the .log files are rotated daily by log4j. This is configurable with /etc/hadoop/conf/log4j.properties. Administrators of a Hadoop cluster should review these logs regularly to look for cluster-specific errors and warnings that might have to do with daemons running incorrectly.  Note that the namenode and secondarynamenode logs should not be deleted more frequently than fs.checkpoint.period, so in the event of a secondarynamenode edits log compaction failure, logs from the namenode and secondarynamenode will be available for diagnostics.
These logs grow slowly when the cluster is idle. When jobs are running, they grow very rapidly. Some problems create considerably more log entries, but some problems only create a few infrequent messages. For example, if the jobtracker can’t connect to the namenode, the jobtracker daemon logs explode with the same error (something like “Retrying connecting to namenode [..]“). Lots of log entries here does not necessarily mean that there is a problem: you have to search through these logs to look for a problem.
·         Job Configuration XML
The job configuration XML logs are created by the jobtracker. The jobtracker creates a .xml file for every job that runs on the cluster. These logs are stored in two places:/var/log/hadoop and /var/log/hadoop/history. The XML file describes the job configuration.
The /hadoop file names are constructed as follows:
job_<job_ID>_conf.xml
For example:
job_200908190029_0001_conf.xml
The /hadoop/history file names are constructed as follows:
<hostname>_<epoch-of-jobtracker-start>_<job-id>_conf.xml
where <hostname> is the hostname of the machine on which the jobtracker is running, <epoch-of-jobtracker-start> is the number of milliseconds that had elapsed since Unix Epoch when the jobtracker daemon was started, and <job-id> is the job ID. For example:
ec2-72-44-61-184.compute-1.amazonaws.com_1250641772616_job_200908190029_0001_conf.xml
These logs are not rotated. These files may be more interesting to developers than system administrators, because their contents are job-specific. You can clear these logs periodically without affecting Hadoop. However, consider archiving the logs if they are of interest in the job-development process. Make sure you do not move or delete a file that is currently being written to by a running job.
Individual job configuration logs are created for each job that is submitted to the cluster. Each log file will be more or less the same size for each job.
·         Job Statistics
These logs are created by the jobtracker. The jobtracker runtime statistics from jobs to these files. Those statistics include task attempts, time spent shuffling, input splits given to task attempts, start times of tasks attempts and other information.
The statistics files are named:
<hostname>_<epoch-of-jobtracker-start>_<job-id>_<job-name>
where <hostname> is the hostname of the machine creating these logs, <epoch-of-jobtracker-start> is the number of milliseconds that had elapsed since Unix Epoch when the jobtracker daemon was started, <job-id> is the job ID, and <job-name> is the name of the job.
For example:
ec2-72-44-61-184.compute-1.amazonaws.com_1250641772616_job_200908190029_0002_hadoop_test-mini-mr
These logs are not rotated.  You can clear these logs periodically without affecting Hadoop. However, consider archiving the logs if they are of interest in the job development process. Make sure you do not move or delete a file that is being written to by a running job.
Individual statistics logs are created for each job that is submitted to the cluster. The size of each log file varies. Jobs with more tasks produce larger files.
·         Standard Error for a particular task attempt
These logs are created by each tasktracker. They contain information written to standard error (stderr) captured when a task attempt is run. These logs can be used for debugging.  For example, a developer can include System.err.println(“some useful information”) calls in the job code. The output will appear in the standard error files.
The parent directory name for these logs is constructed as follows:
/var/log/hadoop/userlogs/attempt_<job-id>_<map-or-reduce>_<attempt-id>
where <job-id> is the ID of the job that this attempt is doing work for, <map-or-reduce> is either “m” if the task attempt was a mapper, or “r” if the task attempt was a reducer, and <attempt-id> is the ID of the task attempt.
For example:
/var/log/hadoop/userlogs/attempt_200908190029_0001_m_000001_0
These logs are rotated according to the mapred.userlog.retain.hours property. You can clear these logs periodically without affecting Hadoop. However, consider archiving the logs if they are of interest in the job development process. Make sure you do not move or delete a file that is being written to by a running job.
The size of these log files depends on the amount of stderr calls used in the job code.
·         Standard Out for a particular task attempt
These logs are very similar to the standard error logs, except they capture stdout instead of stderr. File size depends entirely on how much data the task writes to stdout.
·         log4j informational messages from within the task process
These logs contains anything that log4j writes from within the task process. This includes some Hadoop internal diagnostic info. If the job’s mapper or reducer implementations include call such as LOG.info(), then that output also get written here. Messages can include information about the task, such as how big its record buffer was or how many reduce tasks there are. The size of these log files depends on the number of log4j calls used in the job code.
These logs are rotated according to the mapred.userlog.retain.hours property. You can clear these logs periodically without affecting Hadoop. However, consider archiving the logs if they are of interest in the job development process. Make sure you do not move or delete a file that is being written to by a running job.
The Hadoop components produce the following logs when installing Hadoop from CDH RPM or DEB packages:
·         On the jobtracker:
1
2
3
4
5
6
/var/log/hadoop
              /hadoop-* =&gt; daemon logs
              /job_*.xml =&gt; job configuration XML logs
              /history
                     /*_conf.xml =&gt; job configuration logs
                     &lt; everything else &gt; =&gt; job statistics logs
·         On the namenode:
1
2
/var/log/hadoop
              /hadoop-* =&gt; daemon logs
·         On the secondary namenode:
1
2
/var/log/hadoop
              /hadoop-* =&gt; daemon logs
·         On the datanode:
1
2
/var/log/hadoop
              /hadoop-* =&gt; daemon logs
·         On the tasktracker:
1
2
3
4
5
6
7
/var/log/hadoop
              /hadoop-* =&gt; daemon logs
              /userlogs
                      /attempt_*
                               /stderr =&gt; standard error logs
                               /stdout =&gt; standard out logs
                               /syslog =&gt; log4j logs

It’s probably clear now that Hadoop generates plenty of logs, each with a different purpose and audience.  I hope this post will help you debug your MapReduce jobs and Hadoop cluster.